Vector search: HotKV vs Redis 8 vector sets, from 1 to 100 clients
HotKV and Redis 8.10.2 vector search on 100,000 and 999,000 embeddings from 1 to 100 clients: throughput, latency, recall, loading speed, memory and limits.
Inside HotKV
Engineering notes, benchmarks and product news from the people building HotKV. The results, the methods and what we learned.
6 articles from HotKV Ltd
HotKV and Redis 8.10.2 vector search on 100,000 and 999,000 embeddings from 1 to 100 clients: throughput, latency, recall, loading speed, memory and limits.

AI agent memory is more than a long context window. The four kinds an agent needs, how to store each and what to keep out, with HotKV commands.
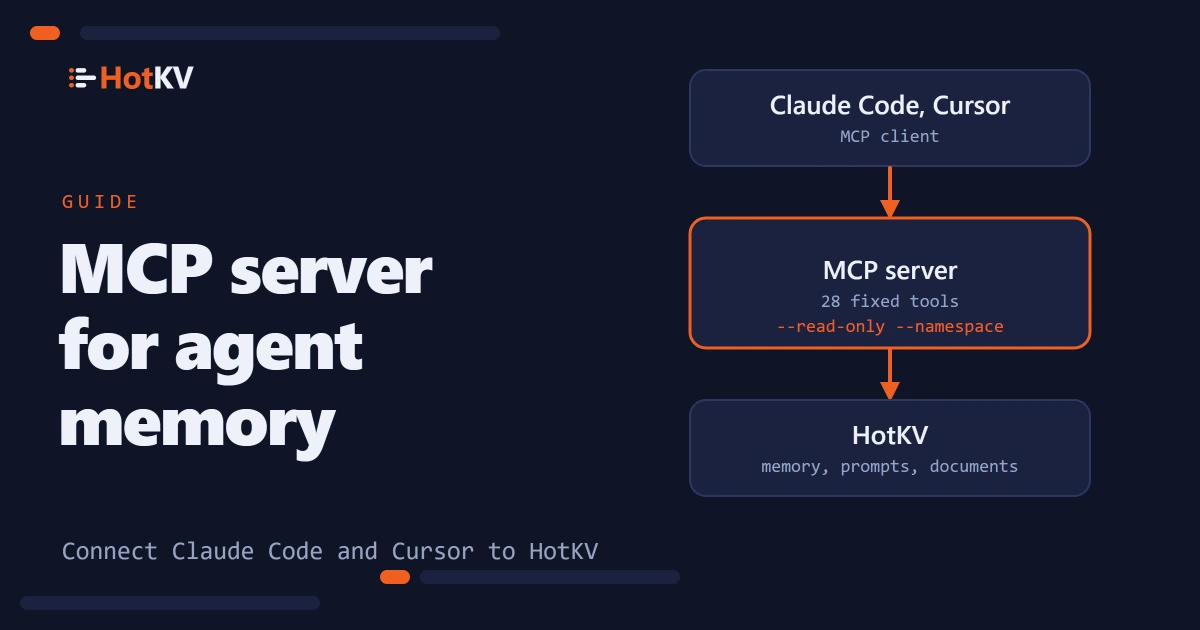
An MCP server gives Claude Code or Cursor memory in HotKV through 28 fixed tools. Install it, connect it and limit it with read-only mode and namespaces.

Prompt caching makes a repeated prefix cheaper. Semantic caching removes the model call. How each works, what we measured and which to use when.

Four Claude models, 3,000 support requests each: HotKV caching cut model calls, tokens and API cost by about 70%. Results and answer-quality trade-offs.
Why I built HotKV, a multithreaded, Redis-compatible data store written from scratch in modern C++, what it offers today and how it did in our benchmark.
Follow your curiosity